How Should Leaders Build an AI Strategy Roadmap with AI Strategy Consulting?

Leaders should build an AI strategy roadmap by focusing on business problems rather than technology, guided by measurable outcomes aligned with organizational priorities like growth, cost control, and quality. AI strategy consulting facilitates identifying practical use cases, assessing data and technology readiness, and managing risk through phased implementation. Prioritization balances value, feasibility, risk, and impact time, ensuring a portfolio of quick wins and long-term projects with clear ownership. Data governance, technical infrastructure, and cross-functional teams are essential foundations, while responsible AI principles—privacy, fairness, transparency, and human oversight—must be embedded from the start. Securing support requires presenting a clear business case, outlining benefits, costs, risks, and dependencies. Implementation follows discovery, design, pilot, deployment, and scaling phases with defined decision points. Success is measured by metrics tied to original business goals and responsible use signals. The roadmap should adapt continuously to evolving AI capabilities, market conditions, and feedback, avoiding common pitfalls like solution-first approaches, inadequate data preparation, and unclear accountability. External consulting can accelerate progress and build internal governance capacity. Overall, an effective AI roadmap is a dynamic, accountable, and strategically aligned plan that drives measurable business value safely and sustainably.
How AI Consulting Services Build Production Systems

AI consulting services transform business challenges into reliable production systems through discovery, design, testing, integration, and continuous improvement. They prioritize automating workflows with clear pain points and manageable complexity, ensuring measurable impact and reduced risk. Consultants assess data quality, technical feasibility, and integration needs before recommending tailored AI solutions, balancing off-the-shelf tools with custom development. Key phases include auditing processes, testing data readiness, building integrated systems with human oversight, and ongoing measurement to optimize performance. Effective AI systems incorporate access controls, monitoring, and escalation paths, supporting trust and compliance. Governance ensures accountability by defining ownership, data usage, and change management. Typical projects launch within 8-12 weeks, focusing on high-ROI workflows that improve efficiency, reduce errors, and enhance customer experience. Leaders are guided to calculate automation value by comparing baseline metrics with post-deployment outcomes, considering both direct savings and indirect benefits. Human review remains essential for critical decisions, blending AI speed with responsible oversight. This structured, practical approach helps organizations avoid costly experiments and build scalable, dependable AI-driven workflows aligned with real business goals.

What Does AI Implementation Consulting Include After Strategy?

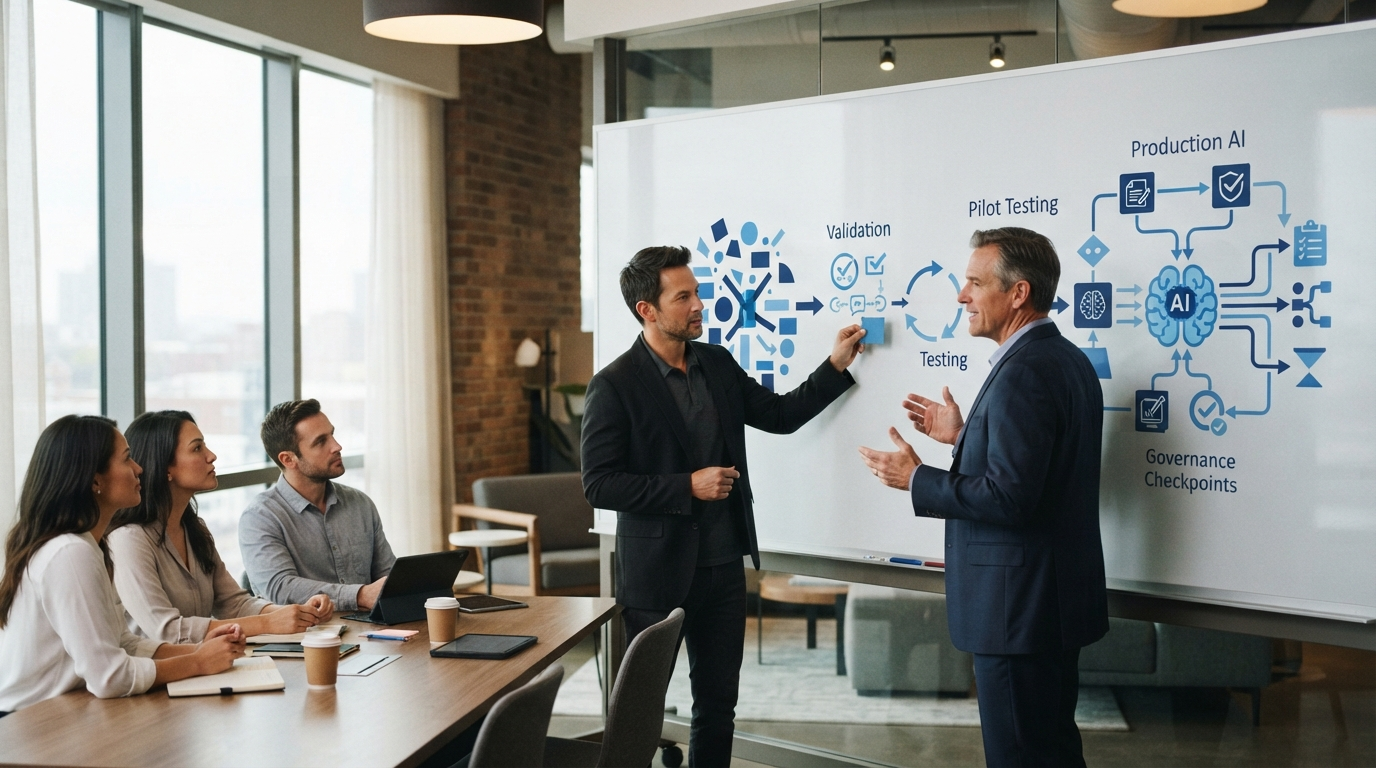
AI implementation consulting translates approved AI strategies into actionable solutions by aligning technology, governance, and processes with business goals. After strategy approval, consultants validate opportunities, set SMART goals, prioritize use cases, and prepare data foundations by ensuring quality, access, and integration. They select appropriate AI models and technologies based on use case needs, balancing build vs. buy options. Governance includes managing data privacy, bias, risk registers, and contingency plans to ensure secure, compliant deployment. Solutions undergo rigorous testing—including pilot phases—and staged deployment with clear adoption support through training and stakeholder engagement. Launch support coordinates teams with monitoring dashboards and user guidance, emphasizing feedback to catch issues early. Continuous monitoring tracks KPIs like model accuracy, cost savings, and customer impact, enabling timely adjustments for data drift or evolving business needs. Ongoing optimization is collaborative, involving tuning, expanding data sources, and scaling use cases. Clients retain ownership of outcomes, roles, and governance responsibilities, supported by consultants’ frameworks and transparent communication. Quality consulting delivers clear roadmaps, realistic expectations, and measurable progress, ensuring AI solutions deliver practical, sustainable value aligned with evolving organizational goals.

Supervised vs unsupervised learning explained with practical scenarios

Supervised and unsupervised learning serve distinct purposes in machine learning projects. Supervised learning requires labeled data to predict known outcomes like churn, fraud, or demand, making it ideal for tasks with clear targets and measurable success. Unsupervised learning, on the other hand, uses unlabeled data to uncover hidden patterns, clusters, or associations, suitable for exploratory tasks such as customer segmentation or anomaly detection without predefined labels. The choice depends on your goal: predict a specific result (supervised) or discover data structure (unsupervised). Labeling cost and data quality also influence this decision—when labels are scarce or expensive, a hybrid approach combining both methods often yields the best results by first exploring data structure, then selectively labeling for supervised training. Supervised models offer clearer validation through known outcomes, while unsupervised models require indirect evaluation and risk over-interpretation. Practical business scenarios highlight these differences: churn and demand prediction favor supervised learning, customer segmentation and market basket analysis rely on unsupervised methods, and anomaly detection may require either approach depending on label availability. Ultimately, choose the method that aligns with your business question, data labeling feasibility, and need for verifiable results, ensuring actionable and trustworthy machine learning outcomes.

How to evaluate a data analytics apprenticeship program before applying?

A strong data analytics apprenticeship program should simultaneously pay you while you learn, provide real-world analytics training, and lead to relevant data roles. Evaluate programs by how closely their projects mimic actual analyst work, the quality of mentoring and feedback, and transparent completion and employment outcomes. Genuine project work involves messy business data, changing requirements, and real stakeholder interaction rather than polished training exercises. Effective mentoring includes regular, personalized feedback from experienced professionals, not just automated or superficial support. Assess curriculum focus on practical, sequential skill-building in Excel, SQL, Python, and data visualization, rather than breadth without depth. Request outcome data like completion rates, retention, and job placement to fairly compare programs, considering your experience level and learning needs. Choose a program aligned with your current gaps: prioritize job-like work if you have some skills but lack experience, supportive mentoring if you’re a career switcher, or strong outcomes if job security is key. Avoid programs with unrealistic entry requirements or vague support. The best apprenticeship offers authentic analyst tasks, dependable mentorship, and clear success metrics, ensuring a meaningful path into data analytics careers.

Machine learning basics for beginners who know some programming

This comprehensive guide introduces machine learning basics for programmers with fundamental coding skills. It emphasizes understanding data, targets, errors, and tradeoffs over syntax. Beginners should start with simple datasets like Iris to grasp classification, regression, preprocessing, and evaluation without being overwhelmed. Essential prerequisites include basic programming for data manipulation, foundational math concepts (algebra, statistics, probability, vectors), and an empirical mindset focused on experimentation. A practical learning sequence is recommended: mastering problem types, workflow steps, supervised learning, core algorithms, unsupervised learning, and then advanced topics. Key learning types include supervised (classification, regression), unsupervised (clustering, dimensionality reduction), and advanced methods like reinforcement learning. The guide stresses the importance of a strong workflow—defining tasks precisely, thorough data inspection, deliberate preprocessing, baseline training, and evaluation on unseen data—to avoid common beginner pitfalls like data leakage and misuse of metrics. Beginners should focus on a few core algorithms (linear/logistic regression, decision trees, random forests, k-NN, naive Bayes) to understand different assumptions and tradeoffs. Project-based learning with classification, regression, and unsupervised tasks builds practical skills. Mastery means confidently handling small datasets, interpreting results, and making informed decisions, laying a solid foundation before advancing to complex models like deep learning.

Data analytics jobs in finance: hiring signals and key tools

Data analytics jobs in finance prioritize a focused technical skillset, finance domain knowledge, and demonstrated business impact. Key hiring signals include strong SQL proficiency for querying and validating financial data, Python or R for automation and advanced analysis, and solid understanding of statistics and econometrics to support forecasting and risk assessment. Finance fluency—knowing financial statements, budgeting, and P&L analysis—enhances credibility, while attention to auditability and data governance reduces hiring risk. Measurable business outcomes, such as improved forecasting accuracy or streamlined reporting, are crucial for standing out. Essential tools include SQL, Excel, Python, R, and Tableau, each serving specific finance tasks. Candidates without direct finance experience should translate their skills into finance-relevant terms, build portfolios with financial metrics, and emphasize governance and decision impact. Entry-level roles focus on foundational technical skills and learning agility, while mid-level roles demand ownership, business judgment, and governance expertise. Interviews assess SQL skills, business judgment, data governance, and communication ability, emphasizing practical problem-solving over technical perfection. Tailoring your profile to the target role—whether financial data analyst, business intelligence analyst, FP&A, or risk analytics—by highlighting relevant skills and outcomes is key. Ultimately, the most hireable candidates combine a clear skill stack, quantitative reasoning, finance context, and governance to inspire trust in handling critical financial decisions.

What is machine learning and why does it work?

Machine learning, a key subfield of artificial intelligence, enables computers to learn patterns from data instead of relying on explicit, hand-written rules. It excels in tackling complex, large-scale, or dynamic problems by training models on examples to make predictions or uncover structures in new data. The core strength of machine learning lies in its ability to generalize—perform well on unseen data—not just memorize training examples. Common types include supervised learning with labeled data, unsupervised learning for uncovering hidden patterns, and reinforcement learning based on trial and error. Successful machine learning depends on quality data, appropriate model-task fit, and constant validation to avoid pitfalls like overfitting, poor data, or distribution shifts. Unlike rigid rule-based systems, machine learning adapts to evolving environments, captures complex variable interactions, and scales with vast datasets. Trustworthy models require clear tasks, relevant training and test data, and known failure modes to ensure reliable real-world performance. Ultimately, machine learning works because real-world data contains usable structure, optimization fine-tunes models, and built-in assumptions guide learning. It thrives when patterns are stable and data-rich, offering powerful solutions where explicit programming becomes impractical.

Data analytics jobs in healthcare: common titles and required skills

Data analytics jobs in healthcare encompass diverse roles, each requiring specific skills and domain knowledge. Key positions include Healthcare Data Analyst, Business Intelligence Analyst, Clinical Data Analyst, Population Health Analyst, Healthcare Quality Analyst, Revenue Cycle Analyst, and Health Data Scientist. Entry-level opportunities often favor Healthcare Data Analyst, Business Intelligence Analyst, and Revenue Cycle Analyst, which balance transferable analytics skills with healthcare-specific knowledge. Essential skills across all roles include proficiency in SQL, Python or R, understanding healthcare data systems (EHR, claims, coding standards like ICD-10), data quality assessment, privacy compliance (HIPAA), and effective communication with clinical and operational teams. Successful candidates demonstrate familiarity with healthcare data’s complexity, regulatory environment, and operational nuances. Building a portfolio with realistic healthcare projects, emphasizing cohort building, data validation, and coding systems, enhances hiring prospects. Advanced roles like Health Data Scientist demand strong programming, statistical modeling, and domain expertise. For those transitioning into healthcare analytics, targeting roles that align with current skills while developing healthcare fluency is crucial. Overall, the best healthcare analytics job is one where existing skills address real-world problems immediately, fostering growth toward more specialized roles.

Finding junior data analyst roles near me and what to ask in interviews

Finding junior data analyst roles near you requires focusing on local fit rather than broad job hunting. Key skills include SQL, Excel, reporting, and clear communication, but success depends on matching the team’s tools, commute, training, and business needs. Entry-level roles often involve recurring reporting, data cleanup, dashboard maintenance, or ad hoc analysis. Screen job postings for specific tools, business area, work type, and logistics to avoid wasting applications on vague or unrealistic listings. Candidates with no direct experience should translate projects and internships into business-relevant examples showcasing practical skills like data cleaning, SQL queries, and stakeholder communication. In interviews, ask about daily tasks, training support, and schedule details to ensure the role fits your expectations. Prepare to demonstrate basic SQL, Excel, dashboard creation, and communication skills, emphasizing clear thinking and attention to detail over advanced coding. Tailor your resume and examples to each local job’s requirements, focusing on quality over quantity in applications. Ultimately, choose a junior data analyst role where your skills align with the work, the team supports your growth, and the commute or hybrid setup is manageable, enabling you to build momentum in your first year.